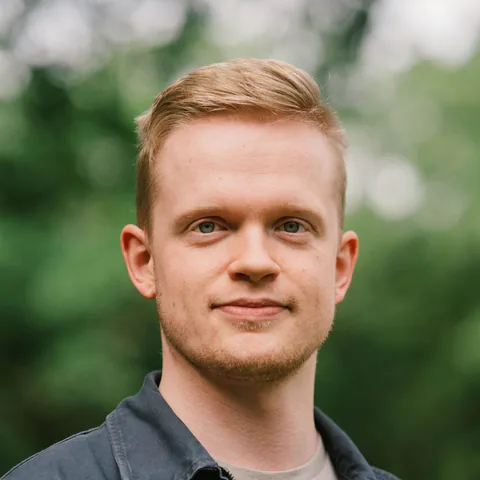
Hello, I'm Casper
I work on AI x Hardware at Normal Computing as an AI Engineer.
More recently before joining Normal Computing, I trained Qwen3 235B to surpass state of the art (GPT-5 and Opus 4.5 back then) on a large cluster of compute. I built the post-training framework, implemented an agent harness, and did data collection/filtering to achieve this result.
More famously, I built a quantization framework called AutoAWQ. Used by Nvidia, AMD, Google, and Intel and officially adopted in the vLLM Project. My project has 3.8 million downloads, 2300+ stars on GitHub, and nearly 10000 models on Hugging Face.
Highlight
I built AutoAWQ in 2023 because the local model community needed a more accurate algorithm while ensuring ease of use and high performance. Reducing bits needed for weights by 70% shifted the bottleneck from compute-bound to memory-bound, allowing 2x faster inference while serving on much less capable hardware. In 2025, I decided to hand off the project to vLLM so they could keep maintaining and improving it.
List of companies who used or referenced AutoAWQ: Nvidia (TensorRT-LLM), Apple (MLX-LM), Intel (AutoRound), Google (Google Cloud), AMD (ROCm Docs), Cohere (vLLM PR), Qwen (Docs).
Writing
DRAM, from one cell to the grid
Multiple Linear Regression: Explained, Coded & Special Cases
We explore the math and code for multiple linear regression, along with the two special cases: simple linear regression and polynomial regression.
Neural Network From Scratch with NumPy and MNIST
Learn the fundamentals of how you can build neural networks without the help of the deep learning frameworks, and instead by using NumPy.
Optimizers Explained - Adam, Momentum and Stochastic Gradient Descent
Picking the right optimizer with the right parameters, can help you squeeze the last bit of accuracy out of your neural network model.
Activation Functions Explained - GELU, SELU, ELU, ReLU and more
Better optimized neural network; choose the right activation function, and your neural network can perform vastly better. 6 activation functions explained.
Neural Networks: Feedforward and Backpropagation Explained & Optimization
What are neural networks? Developers should understand backpropagation, to figure out why their code sometimes does not work. Visual and down to earth explanation of the math of backpropagation.
How to do Linear Regression and Logistic Regression in Machine Learning?
Wondering how Linear Regression or Logistic Regression works in Machine Learning? Python code and a walkthrough of both concepts are available here.
Probability Theory: Bayes Theorem, Sum Rule and Product Rule
Probability is important in ML. Here I explain the basics of the sum rule, product rule and a longer section on Bayes' theorem and marginalization
Statistics Basics - Variance and Standard Deviation
This part is all about statistics, which is undoubtedly used all over Machine Learning. I explain the terms and give you a function to fill missing data.
Principal Component Analysis (PCA) and Singular Value Decomposition (SVD)
What is Principal Component Analysis (PCA)? What line accounts for the most variance? What is Singular Value Decomposition (SVD)?
Linear Algebra Basics 4: Determinant, Cross Product and Dot Product
Visualizing the determinant, cross product and dot product can be hard. Come read the intuitive way of understanding these three pieces from Linear Algebra.
Linear Algebra Basics 3: Linear Transformations and Matrix Multiplication
What are Linear Transformations? What is Vector Space? How to do Vector Multiplication (Matrix Multiplication)? Conceptualizing a Linear Transformation is also key to understanding a transformation, so ..
Linear Algebra Basics 2: Basis Vectors, Span and Linear Combinations
What are basis vectors? Why are they so important? What is Span and a Linear Combination? Come read, quick recap at the bottom.
Linear Algebra Basics 1: Vectors, Vector Addition and Scalars
What is a vector? How to think about vectors? What is vector addition? What is a scalar? Come find the answers here.